The AI Price War Is On: Claude Haiku 5.5, Mistral’s ‘Le Chonk,’ and the Week AI Got Cheap
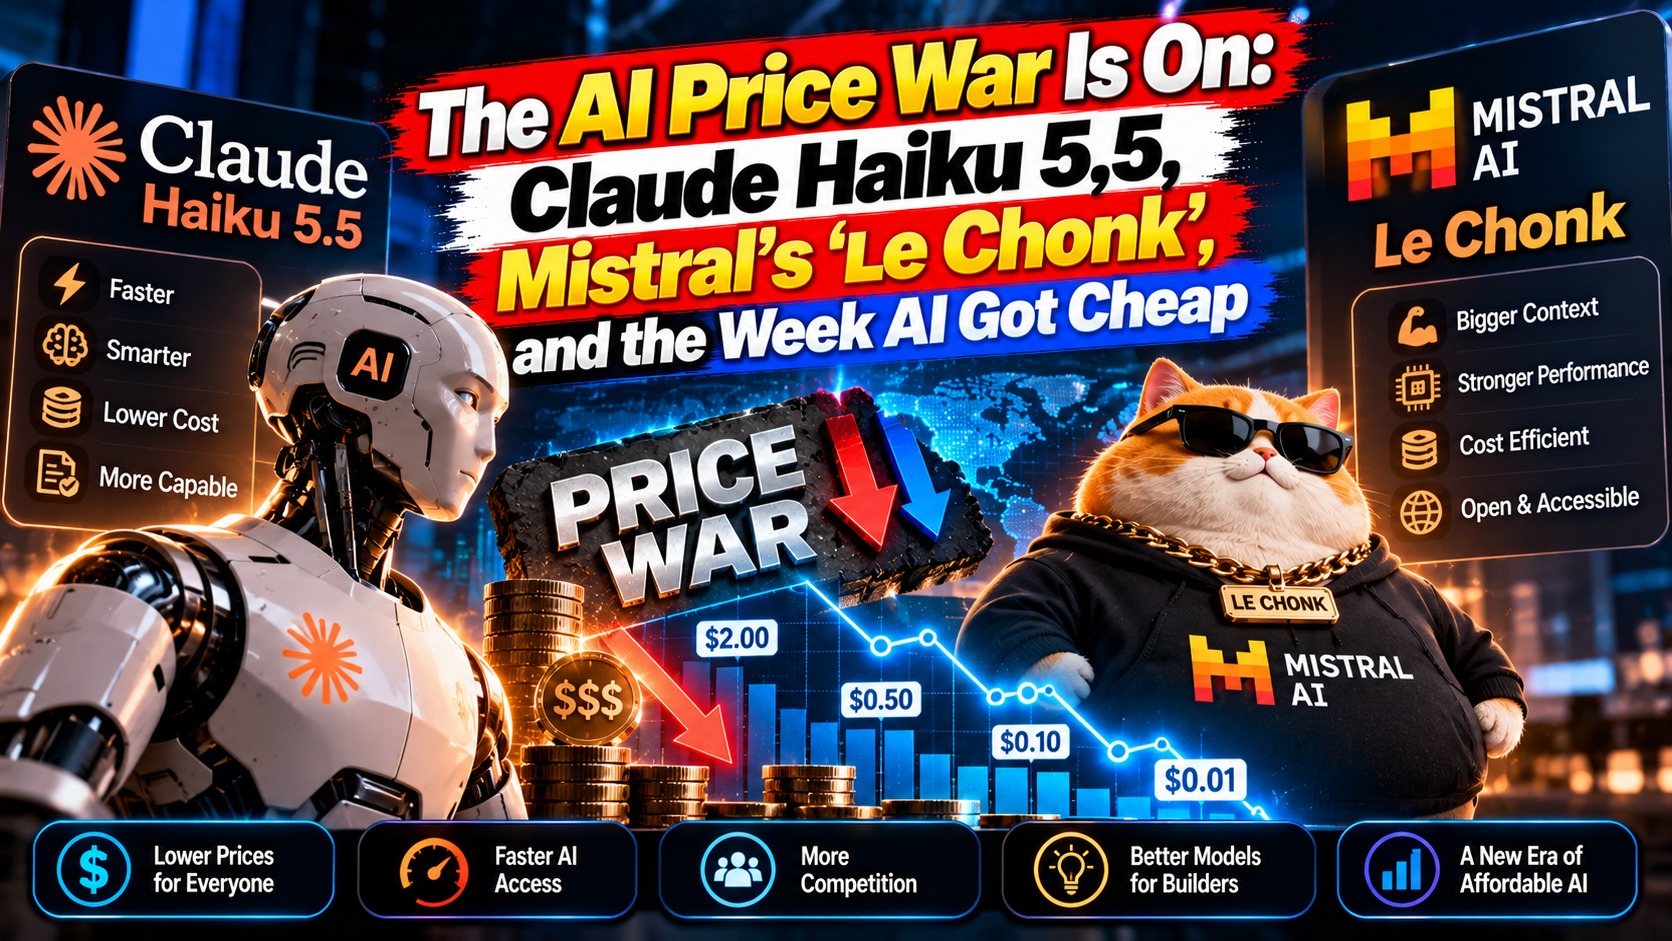
Something remarkable happened in AI this week: the models got better and cheaper at the same time. Anthropic launched Claude Haiku 5.5 at prices matching OpenAI’s cheapest tier. Mistral unveiled a trillion-parameter open model. An Nvidia-backed startup teased a 501-billion-parameter open-weight model. And an AI agent startup raised half a billion dollars after walking away from a Meta acquisition. Felt the ground shifting under the AI industry this week? You weren’t imagining it.
Claude Haiku 5.5: The Price War Shot Heard Round the Industry
On October 7, Anthropic launched Claude Haiku 5.5 — its smallest, fastest, cheapest model — at $0.10 per million input tokens and $0.50 per million output tokens. Those numbers match OpenAI’s GPT-6 Luna pricing exactly. And that matching is the story. Not a coincidence. Competition.
Haiku models are the workhorses of the AI world. Not the smartest — but fast and cheap enough to embed in everything: customer support bots, code autocomplete, document processing at scale. When this tier gets cheaper, AI shows up in more products, because the unit economics suddenly work for use cases that were marginal before. A support bot handling millions of queries a month cares enormously about the difference between $0.10 and $1.00 per million tokens.
Anthropic also halved the cache-read price for Sonnet 5.5, the mid-tier model. Prompt caching — reusing previously computed context — is one of the industry’s quiet efficiency revolutions. For agents and long conversations, cached context can be most of your token usage, so halving its price cuts real-world costs in a meaningful way. The message to developers: build bigger, longer-running AI applications. The economics support it now.
Mistral’s ‘Le Chonk’: Europe’s Trillion-Parameter Answer
On October 6 in Abu Dhabi, Mistral launched Large 4 — nicknamed “Le Chonk” — a roughly one-trillion-parameter multimodal mixture-of-experts model with about 49 billion active parameters per token, reportedly trained on some 3,800 Grace Blackwell GPUs. Weights are expected on Hugging Face by end of October.
A few things matter here. First, the scale. A trillion parameters puts Mistral in the frontier-model conversation with the biggest American and Chinese labs. For a European company running on a fraction of its rivals’ funding, that’s a genuine achievement. Second, the mixture-of-experts architecture: only 49B of the trillion parameters fire per token, which means frontier-class capability at a fraction of the inference cost of a dense model. MoE is the industry’s answer to the scaling-cost problem, and everyone’s converging on it.
Third, the open weights. Mistral putting weights on Hugging Face continues its strategy of being the open alternative to closed American labs — a positioning with real geopolitical weight in Europe, where AI sovereignty is policy, not just a talking point. An open trillion-parameter model anyone can download, fine-tune, and deploy is a meaningful counterweight to the closed-API world. And the Abu Dhabi venue is its own signal: Gulf states are pouring money into AI infrastructure, and Mistral is happy to take meetings where the compute funding lives.
Reflection AI’s Beam: The $25 Billion Bet on Open Weights
Speaking of open weights — Reflection AI, founded by ex-DeepMind researchers and backed with over $4 billion at a valuation around $25 billion, unveiled Beam: a 501-billion-parameter sparse mixture-of-experts model with 23 billion active parameters per token, due out under the Apache 2.0 license after red-teaming.
Read that valuation again: $25 billion for a company whose flagship product is a model it plans to give away under Apache 2.0. That’s the open-weights business model in its purest form. The bet: whoever creates the standard open model captures enormous value in services, enterprise deployments, and ecosystem influence — even with the weights themselves free. The Red Hat thesis, applied to AI, at unprecedented scale.
The ex-DeepMind pedigree matters. DeepMind alumni have founded some of the most credible AI startups on the planet, and the market is pricing that talent accordingly. Is $25 billion sane for a pre-revenue lab? That’s a question for venture capitalists. For the rest of us, the practical news is simpler: another frontier-class open model is coming, and the open ecosystem keeps getting stronger.
Manus: Half a Billion After Walking Away From Meta
The week’s wildest business story: AI agent startup Manus (built by Butterfly Effect) raised over $500 million on October 8 — after unwinding a Meta acquisition reportedly worth more than $2 billion. Boyu Capital and IDG Capital co-led, with Tencent and HSG participating.
Walking away from $2B+ to raise $500M independently takes extraordinary confidence. Or extraordinary stubbornness. The logic, presumably: the team thinks Manus can be worth far more standalone than as a Meta division — and in today’s funding climate for agent startups, they might be right. AI agents are the industry’s consensus next platform shift, and Manus has real traction and mindshare.
The unwound Meta deal says something about Meta’s acquisition appetite, too: the company’s hunting aggressively for AI talent and products, willing to pay billions. With the TikTok ad ban and the glasses push happening at the same time, Meta’s October has been a case study in a company fighting on every front at once.
What the Price War Means for You
Why should any of this matter if you’re not an AI developer? Because the price war flows downhill — to free tiers and cheap products. Every time the frontier labs cut API prices, consumer AI economics improve: better free assistants, cheaper AI features in the apps you already use, more startups able to build AI products without torching cash on inference.
The pattern of the last two years is clear. Model capability goes up, model cost goes down, and the benefits spread outward. Today’s trillion-parameter models are 2028’s free-tier models. And the open-weights releases mean this spread isn’t controlled by three companies — it’s a real ecosystem.
For developers and builders, the practical advice: don’t over-optimize for today’s prices. They’re falling fast enough that architectures built around expensive inference will look quaint within a year. Build for capability; let the price curve come to you. And keep an eye on the open models — the gap between open and closed keeps narrowing, and open gives you something closed never will: control. For ongoing AI coverage, follow our Tech News and AI Tools sections.
Related Reading
Keep exploring: ChatGPT vs Claude vs Gemini: Which AI Should You Actually Pay For?, How to Write Better ChatGPT Prompts: 7 Techniques That Actually Work, and Best AI Meeting Note Takers in 2026.